# Strange memory leak ElasticSearch
**URL:** https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814
**Category:** Elasticsearch
**Created:** [December 16, 2020, 8:03am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814 "2020-12-16T08:03:10Z")
**Posts on this page:** 20
**Page:** 1
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 16, 2020, 8:03am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/1 "2020-12-16T08:03:10Z")
Hi, we have a cluster of ES.
Our Heap is 31 Gb on each node. Total RAM 128 Gb on each node.
And our RAM fills up over time and starts to run out, it that time we get faults of cluster.
We see that "cached" constantly growing and in times of run out equals "free".

Have anyone any ideas why it may be and what's going on?
---
### Author:  [@DavidTurner](https://discuss.elastic.co/u/DavidTurner)
#### Post date: [December 16, 2020, 8:35am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/2 "2020-12-16T08:35:47Z")
That's normal for Linux, it just means any spare memory is being used for temporary things like the filesystem cache.
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 16, 2020, 8:47am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/3 "2020-12-16T08:47:47Z")
Not normal, that in time of RAM run out we have cluster faults. When we clean cache it comes normal again.
---
### Author:  [@Christian\_Dahlqvist](https://discuss.elastic.co/u/Christian_Dahlqvist)
#### Post date: [December 16, 2020, 9:05am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/4 "2020-12-16T09:05:29Z")
It is normal. How are you running your cluster? Bare-metal hardware? VMs? Cloud? Containers?
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 16, 2020, 9:55am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/5 "2020-12-16T09:55:39Z")
It's metal. Now we increasing vfs\_cache\_pressure setting of OS. Seems like it helps
---
### Author:  [@warkolm](https://discuss.elastic.co/u/warkolm)
#### Post date: [December 16, 2020, 10:16pm UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/6 "2020-12-16T22:16:57Z")
> [@ThreatInter](#):
>
> that in time of RAM run out we have cluster faults
What sort of faults are you seeing?
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 17, 2020, 3:08am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/7 "2020-12-17T03:08:13Z")
Connection timeouts from source, when it tryies to write to ES, and "channel closed" messages in logs of elastic nodes, sometimes nodes leaving cluster
---
### Author:  [@warkolm](https://discuss.elastic.co/u/warkolm)
#### Post date: [December 17, 2020, 3:32am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/8 "2020-12-17T03:32:52Z")
Sharing those would be useful.
As would the output of `_cluster/stats?human&pretty`.
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 17, 2020, 3:55am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/9 "2020-12-17T03:55:12Z")
Faults are described here
> [@Elastic cluster "Received ban for the parent \[channel closed\]", Apache Metron "listener timeout after waiting for"](https://discuss.elastic.co/t/elastic-cluster-received-ban-for-the-parent-channel-closed-apache-metron-listener-timeout-after-waiting-for/258535):
>
> Hello, we using ES cluster with 3 nodes, each datanode. We faced with problem that sometimes we can't write into our cluster using Apache Metron : java.io.IOException: listener timeout after waiting for [60000] ms at org.elasticsearch.client.RestClient$SyncResponseListener.get(RestClient.java:660) at org.elasticsearch.client.RestClient.performRequest(RestClient.java:219) at org.elasticsearch.client.RestClient.performRequest(RestClient.java:191) at org.elasticsearch.client.RestHighLevelClient.pe…
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 17, 2020, 3:59am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/10 "2020-12-17T03:59:51Z")
\_cluster/stats?human&pretty:
```auto
{
"_nodes" : {
"total" : 3,
"successful" : 3,
"failed" : 0
},
"cluster_name" : "h1",
"cluster_uuid" : "s71YMgBeQhyRUyYVIzX2sg",
"timestamp" : 1608177516321,
"status" : "green",
"indices" : {
"count" : 646,
"shards" : {
"total" : 2851,
"primaries" : 1770,
"replication" : 0.6107344632768361,
"index" : {
"shards" : {
"min" : 1,
"max" : 10,
"avg" : 4.413312693498452
},
"primaries" : {
"min" : 1,
"max" : 5,
"avg" : 2.739938080495356
},
"replication" : {
"min" : 0.0,
"max" : 2.0,
"avg" : 0.7631578947368421
}
}
},
"docs" : {
"count" : 7128542981,
"deleted" : 47654
},
"store" : {
"size" : "9.3tb",
"size_in_bytes" : 10305383653790,
"reserved" : "0b",
"reserved_in_bytes" : 0
},
"fielddata" : {
"memory_size" : "206.1mb",
"memory_size_in_bytes" : 216186160,
"evictions" : 0
},
"query_cache" : {
"memory_size" : "2.3gb",
"memory_size_in_bytes" : 2492159398,
"total_count" : 194493637,
"hit_count" : 4816136,
"miss_count" : 189677501,
"cache_size" : 81248,
"cache_count" : 89063,
"evictions" : 7815
},
"completion" : {
"size" : "0b",
"size_in_bytes" : 0
},
"segments" : {
"count" : 45997,
"memory" : "1.2gb",
"memory_in_bytes" : 1338770608,
"terms_memory" : "984mb",
"terms_memory_in_bytes" : 1031834704,
"stored_fields_memory" : "130.2mb",
"stored_fields_memory_in_bytes" : 136538312,
"term_vectors_memory" : "0b",
"term_vectors_memory_in_bytes" : 0,
"norms_memory" : "56.2mb",
"norms_memory_in_bytes" : 59000704,
"points_memory" : "0b",
"points_memory_in_bytes" : 0,
"doc_values_memory" : "106.2mb",
"doc_values_memory_in_bytes" : 111396888,
"index_writer_memory" : "182.9mb",
"index_writer_memory_in_bytes" : 191827088,
"version_map_memory" : "0b",
"version_map_memory_in_bytes" : 0,
"fixed_bit_set" : "67.4kb",
"fixed_bit_set_memory_in_bytes" : 69072,
"max_unsafe_auto_id_timestamp" : 1608145213074,
"file_sizes" : { }
},
"mappings" : {
"field_types" : [
{
"name" : "boolean",
"count" : 1652,
"index_count" : 389
},
{
"name" : "date",
"count" : 4004,
"index_count" : 644
},
{
"name" : "double",
"count" : 4,
"index_count" : 1
},
{
"name" : "float",
"count" : 623,
"index_count" : 301
},
{
"name" : "geo_point",
"count" : 1057,
"index_count" : 141
},
{
"name" : "integer",
"count" : 739,
"index_count" : 67
},
{
"name" : "ip",
"count" : 2320,
"index_count" : 404
},
{
"name" : "keyword",
"count" : 114137,
"index_count" : 643
},
{
"name" : "long",
"count" : 9445,
"index_count" : 627
},
{
"name" : "nested",
"count" : 169,
"index_count" : 94
},
{
"name" : "object",
"count" : 31513,
"index_count" : 621
},
{
"name" : "text",
"count" : 19739,
"index_count" : 635
}
]
},
"analysis" : {
"char_filter_types" : [],
"tokenizer_types" : [],
"filter_types" : [],
"analyzer_types" : [],
"built_in_char_filters" : [],
"built_in_tokenizers" : [],
"built_in_filters" : [],
"built_in_analyzers" : []
}
},
"nodes" : {
"count" : {
"total" : 3,
"coordinating_only" : 0,
"data" : 3,
"ingest" : 3,
"master" : 3,
"remote_cluster_client" : 3
},
"versions" : [
"7.9.1"
],
"os" : {
"available_processors" : 144,
"allocated_processors" : 144,
"names" : [
{
"name" : "Linux",
"count" : 3
}
],
"pretty_names" : [
{
"pretty_name" : "CentOS Linux 7 (Core)",
"count" : 3
}
],
"mem" : {
"total" : "376.8gb",
"total_in_bytes" : 404655390720,
"free" : "3gb",
"free_in_bytes" : 3268222976,
"used" : "373.8gb",
"used_in_bytes" : 401387167744,
"free_percent" : 1,
"used_percent" : 99
}
},
"process" : {
"cpu" : {
"percent" : 11
},
"open_file_descriptors" : {
"min" : 11423,
"max" : 11803,
"avg" : 11657
}
},
"jvm" : {
"max_uptime" : "2.6d",
"max_uptime_in_millis" : 228990188,
"versions" : [
{
"version" : "14.0.1",
"vm_name" : "OpenJDK 64-Bit Server VM",
"vm_version" : "14.0.1+7",
"vm_vendor" : "AdoptOpenJDK",
"bundled_jdk" : true,
"using_bundled_jdk" : true,
"count" : 3
}
],
"mem" : {
"heap_used" : "55.2gb",
"heap_used_in_bytes" : 59319432448,
"heap_max" : "93gb",
"heap_max_in_bytes" : 99857989632
},
"threads" : 1302
},
"fs" : {
"total" : "21.4tb",
"total_in_bytes" : 23627102601216,
"free" : "12.1tb",
"free_in_bytes" : 13314248302592,
"available" : "11tb",
"available_in_bytes" : 12113912176640
},
...
```
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 18, 2020, 7:50am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/11 "2020-12-18T07:50:06Z")
Is it possible to limit cache usage of elastic by playing with indices.fielddata.cache.size setting?
---
### Author:  [@Christian\_Dahlqvist](https://discuss.elastic.co/u/Christian_Dahlqvist)
#### Post date: [December 18, 2020, 8:12am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/12 "2020-12-18T08:12:48Z")
That only limits the caching that is done on the heap within Elasticsearch. To tune page cache usage at the operating system level you need to tune the operating system, not Elasticsearch.
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 18, 2020, 9:10am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/13 "2020-12-18T09:10:28Z")
ok, thank you
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 21, 2020, 10:30am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/14 "2020-12-21T10:30:52Z")
Well, sometimes we also get this error:
```auto
[2020-12-21T14:59:24,543][DEBUG][o.e.m.j.JvmGcMonitorService] [h1-es01] [gc][511559] overhead, spent [133ms] collecting in the last [1s]
```
Full GC log here:[https://github.com/NailBash/just\_log/blob/main/gc.log](https://github.com/NailBash/just_log/blob/main/gc.log)
Is it mean that we have problem in gc?
---
### Author:  [@DavidTurner](https://discuss.elastic.co/u/DavidTurner)
#### Post date: [December 21, 2020, 12:08pm UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/15 "2020-12-21T12:08:19Z")
> [@ThreatInter](#):
>
> Is it mean that we have problem in gc?
No, this is a `DEBUG` log which [the manual says](https://www.elastic.co/guide/en/elasticsearch/reference/current/logging.html#configuring-logging-levels) is "only intended for expert use".
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 22, 2020, 9:23am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/16 "2020-12-22T09:23:15Z")
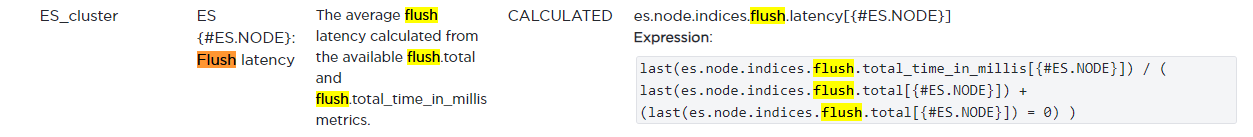
Also our flush latency is bigger than 100 ms. Can it indicate that our problem is something certain?
---
### Author:  [@DavidTurner](https://discuss.elastic.co/u/DavidTurner)
#### Post date: [December 22, 2020, 10:58am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/17 "2020-12-22T10:58:24Z")
What do you mean "flush latency"?
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 22, 2020, 11:10am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/18 "2020-12-22T11:10:25Z")
This metric
---
### Author:  [@DavidTurner](https://discuss.elastic.co/u/DavidTurner)
#### Post date: [December 22, 2020, 11:24am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/19 "2020-12-22T11:24:58Z")
100ms sounds fairly normal for that metric.
---
### Author:  [@ThreatInter](https://discuss.elastic.co/u/ThreatInter)
#### Post date: [December 24, 2020, 5:15am UTC](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814/20 "2020-12-24T05:15:18Z")
well, we have this message
```auto
[2020-12-23T14:11:12,026][INFO][o.e.m.j.JvmGcMonitorService] [h1-es02] [gc][764620] overhead, spent [296ms] collecting in the last [1s]
[2020-12-23T14:12:10,536][INFO][o.e.m.j.JvmGcMonitorService] [h1-es02] [gc][764678] overhead, spent [365ms] collecting in the last [1s]
[2020-12-23T14:12:12,537][INFO][o.e.m.j.JvmGcMonitorService] [h1-es02] [gc][764680] overhead, spent [312ms] collecting in the last [1s]
[2020-12-23T14:13:55,376][DEBUG][o.e.m.j.JvmGcMonitorService] [h1-es02] [gc][764782] overhead, spent [117ms] collecting in the last [1s]
```
and then
```auto
[2020-12-23T14:14:30,931][DEBUG][o.e.c.c.LeaderChecker] [h1-es02] 1 consecutive failures (limit [cluster.fault_detection.leader_check.retry_count] is 3) with leader [{h1-es03}{Qshtg7-TQIyxeiccpkmlIA}{3Yj31P_rSmCMjymjRtyyEQ}{h1-es03ip}{h1-es03ip:9300}{dimr}]
```
could it be related?
We periodically receive second messages and can't understand why, network seems to be ok. This messages usually appear in time of higher load on cluster, and sometimes node left the cluster. In atop log we don't see any real problem: ram, disks IO, CPU all is ok too.
P.S. Sometimes we even don't receive information about CPU, network from failed node by Zabbix.
[Next page](https://discuss.elastic.co/t/strange-memory-leak-elasticsearch/258814.md?page=2)